Works with the MCP server your analytics agent already uses
Add it to honest_agent_config.yml with a URL or a local command, and pick the model your agent runs on. One target per agent, like a dbt profile.
Close the loop, from test to action
version: 1evals: - category: sales grading: method: extract_match # code compares the value min_score: 0.8 provenance: min_score: 0.7 tests: - id: revenue_q4 title: Revenue in Q4 2026 prompt: What was our revenue in Q4 2026, net of discounts and before tax? expected_answer: "307992639.49" provenance: expected_sources: [lineitem, warehouse.main.orders] - id: order_total_2026 title: Order total in 2026 expected_answer: "35055813985.22"
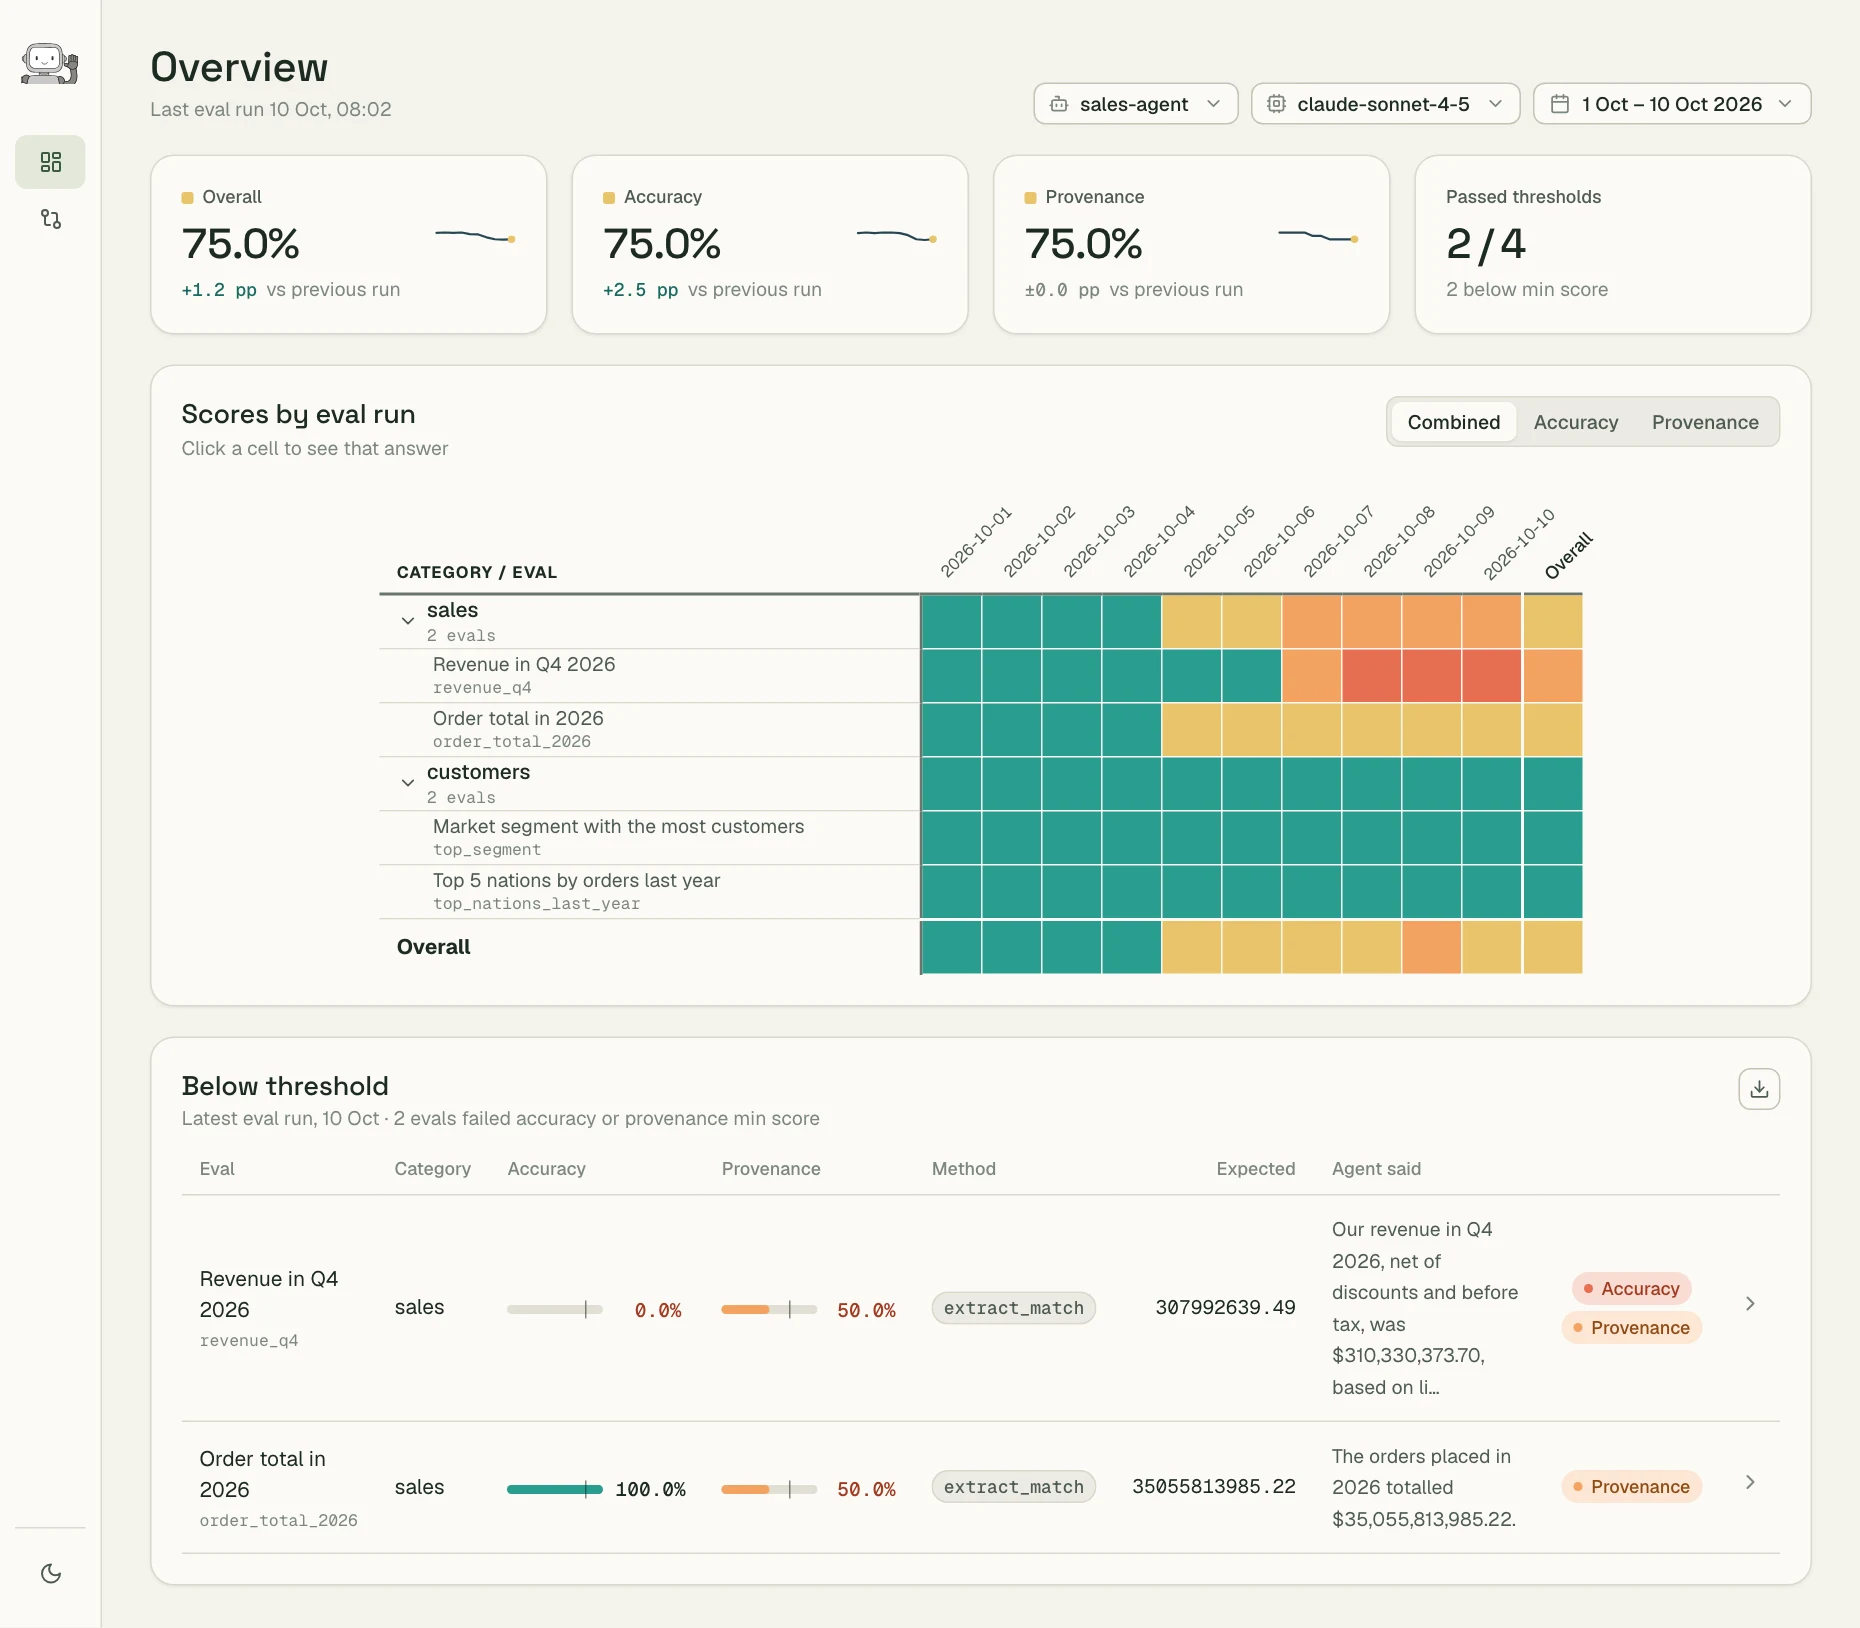
Overview
Last eval run Oct 10, 08:02
Scores by eval run
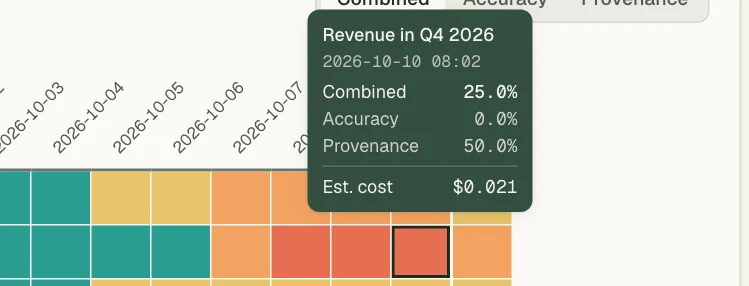
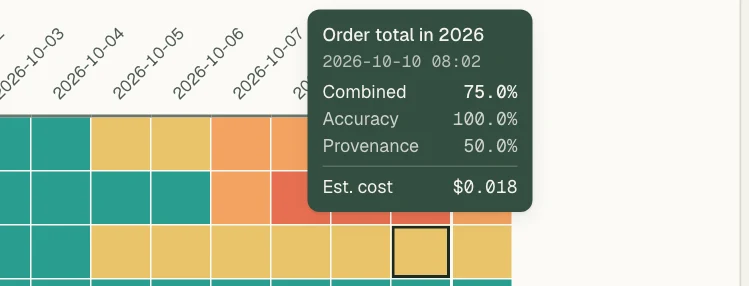
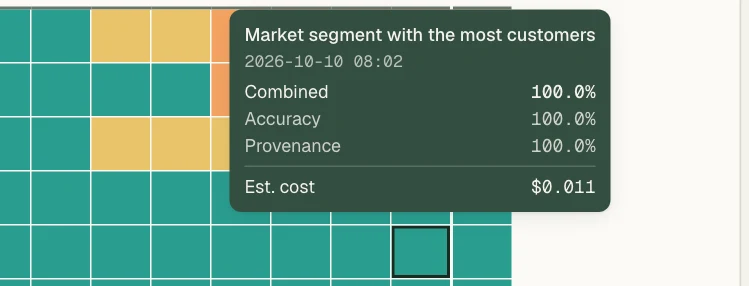
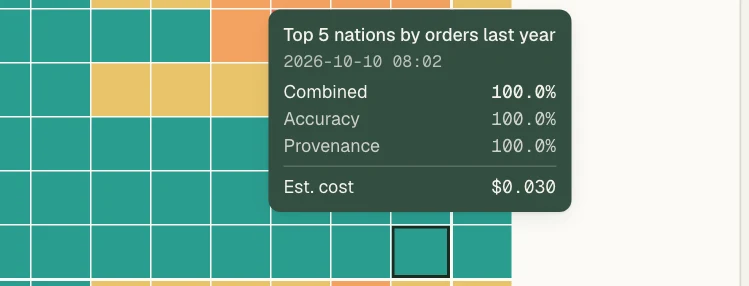
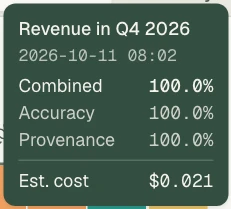
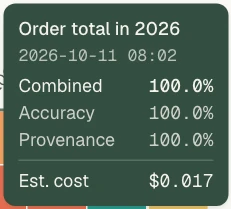
Hover a cell to see its scores
| Category / Eval | 2026-10-0710-07 | 2026-10-0810-08 | 2026-10-0910-09 | 2026-10-1010-10 | Overall |
|---|---|---|---|---|---|
sales 2 evals | sales 2026-10-07 Combined75.0% Accuracy100.0% Provenance50.0% Est. cost$0.018 | sales 2026-10-08 Combined100.0% Accuracy100.0% Provenance100.0% Est. cost$0.018 | sales 2026-10-09 Combined75.0% Accuracy100.0% Provenance50.0% Est. cost$0.018 | sales 2026-10-10 Combined50.0% Accuracy50.0% Provenance50.0% Est. cost$0.039 | sales Overall Combined75.0% Accuracy87.5% Provenance62.5% |
revenue_q4 Revenue in Q4 2026 | revenue_q4 2026-10-07 No run | revenue_q4 2026-10-08 No run | revenue_q4 2026-10-09 No run | revenue_q4 2026-10-10 Combined25.0% Accuracy0.0% Provenance50.0% Est. cost$0.021 | revenue_q4 Overall Combined25.0% Accuracy0.0% Provenance50.0% |
order_total_2026 Order total in 2026 | order_total_2026 2026-10-07 Combined75.0% Accuracy100.0% Provenance50.0% Est. cost$0.018 | order_total_2026 2026-10-08 Combined100.0% Accuracy100.0% Provenance100.0% Est. cost$0.018 | order_total_2026 2026-10-09 Combined75.0% Accuracy100.0% Provenance50.0% Est. cost$0.018 | order_total_2026 2026-10-10 Combined75.0% Accuracy100.0% Provenance50.0% Est. cost$0.018 | order_total_2026 Overall Combined81.2% Accuracy100.0% Provenance62.5% |
customers 2 evals | customers 2026-10-07 Combined65.0% Accuracy50.0% Provenance80.0% Est. cost$0.041 | customers 2026-10-08 Combined77.5% Accuracy55.0% Provenance100.0% Est. cost$0.042 | customers 2026-10-09 Combined77.5% Accuracy55.0% Provenance100.0% Est. cost$0.043 | customers 2026-10-10 Combined97.5% Accuracy95.0% Provenance100.0% Est. cost$0.041 | customers Overall Combined79.4% Accuracy63.7% Provenance95.0% |
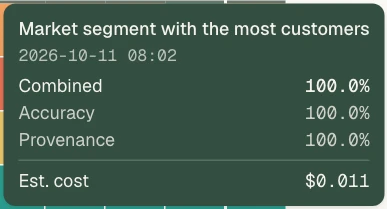
top_segment Market segment with the most customers | top_segment 2026-10-07 Combined100.0% Accuracy100.0% Provenance100.0% Est. cost$0.011 | top_segment 2026-10-08 Combined100.0% Accuracy100.0% Provenance100.0% Est. cost$0.012 | top_segment 2026-10-09 Combined100.0% Accuracy100.0% Provenance100.0% Est. cost$0.012 | top_segment 2026-10-10 Combined100.0% Accuracy100.0% Provenance100.0% Est. cost$0.011 | top_segment Overall Combined100.0% Accuracy100.0% Provenance100.0% |
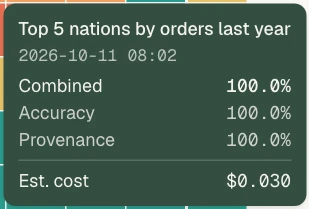
top_nations_last_year Nations with the most orders last year | top_nations_last_year 2026-10-07 Combined30.0% Accuracy0.0% Provenance60.0% Est. cost$0.030 | top_nations_last_year 2026-10-08 Combined55.0% Accuracy10.0% Provenance100.0% Est. cost$0.031 | top_nations_last_year 2026-10-09 Combined55.0% Accuracy10.0% Provenance100.0% Est. cost$0.031 | top_nations_last_year 2026-10-10 Combined95.0% Accuracy90.0% Provenance100.0% Est. cost$0.030 | top_nations_last_year Overall Combined58.8% Accuracy27.5% Provenance90.0% |
Overall | Overall 2026-10-07 Combined68.3% Accuracy66.7% Provenance70.0% Est. cost$0.059 | Overall 2026-10-08 Combined85.0% Accuracy70.0% Provenance100.0% Est. cost$0.060 | Overall 2026-10-09 Combined76.7% Accuracy70.0% Provenance83.3% Est. cost$0.061 | Overall 2026-10-10 Combined73.8% Accuracy72.5% Provenance75.0% Est. cost$0.080 | Overall Overall Combined75.9% Accuracy69.8% Provenance82.1% |
Below threshold
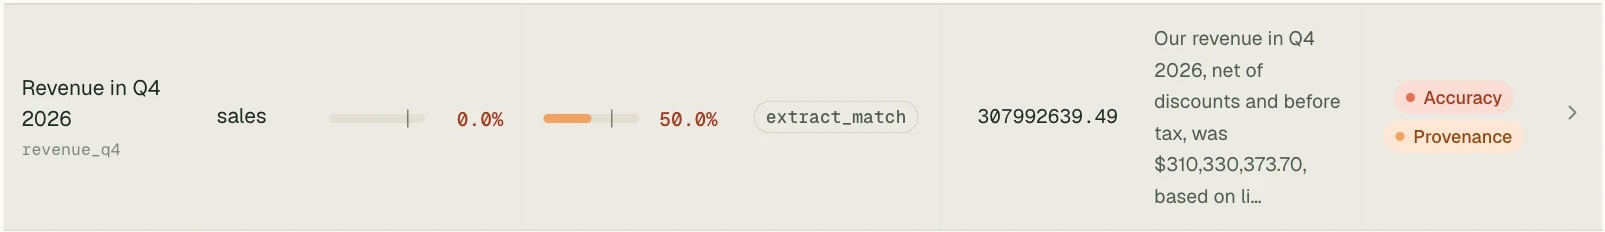
Latest eval run, Oct 10 · 2 evals failed accuracy or provenance min score
| Eval | Category | Accuracy | Provenance | |
|---|---|---|---|---|
Revenue in Q4 2026 revenue_q4 | sales | 0.0% | 50.0% | AccuracyProvenance |
Order total in 2026 order_total_2026 | sales | 100.0% | 50.0% | Provenance |
🔴 2 of 4 evals below threshold
Define what a right answer looks like
Every eval is a question you already know the answer to. honest-agent always checks that the answer is correct (accuracy), and can also check that it came from the right sources (provenance).
contains
Passes when the expected answer appears in the reply. No model call.
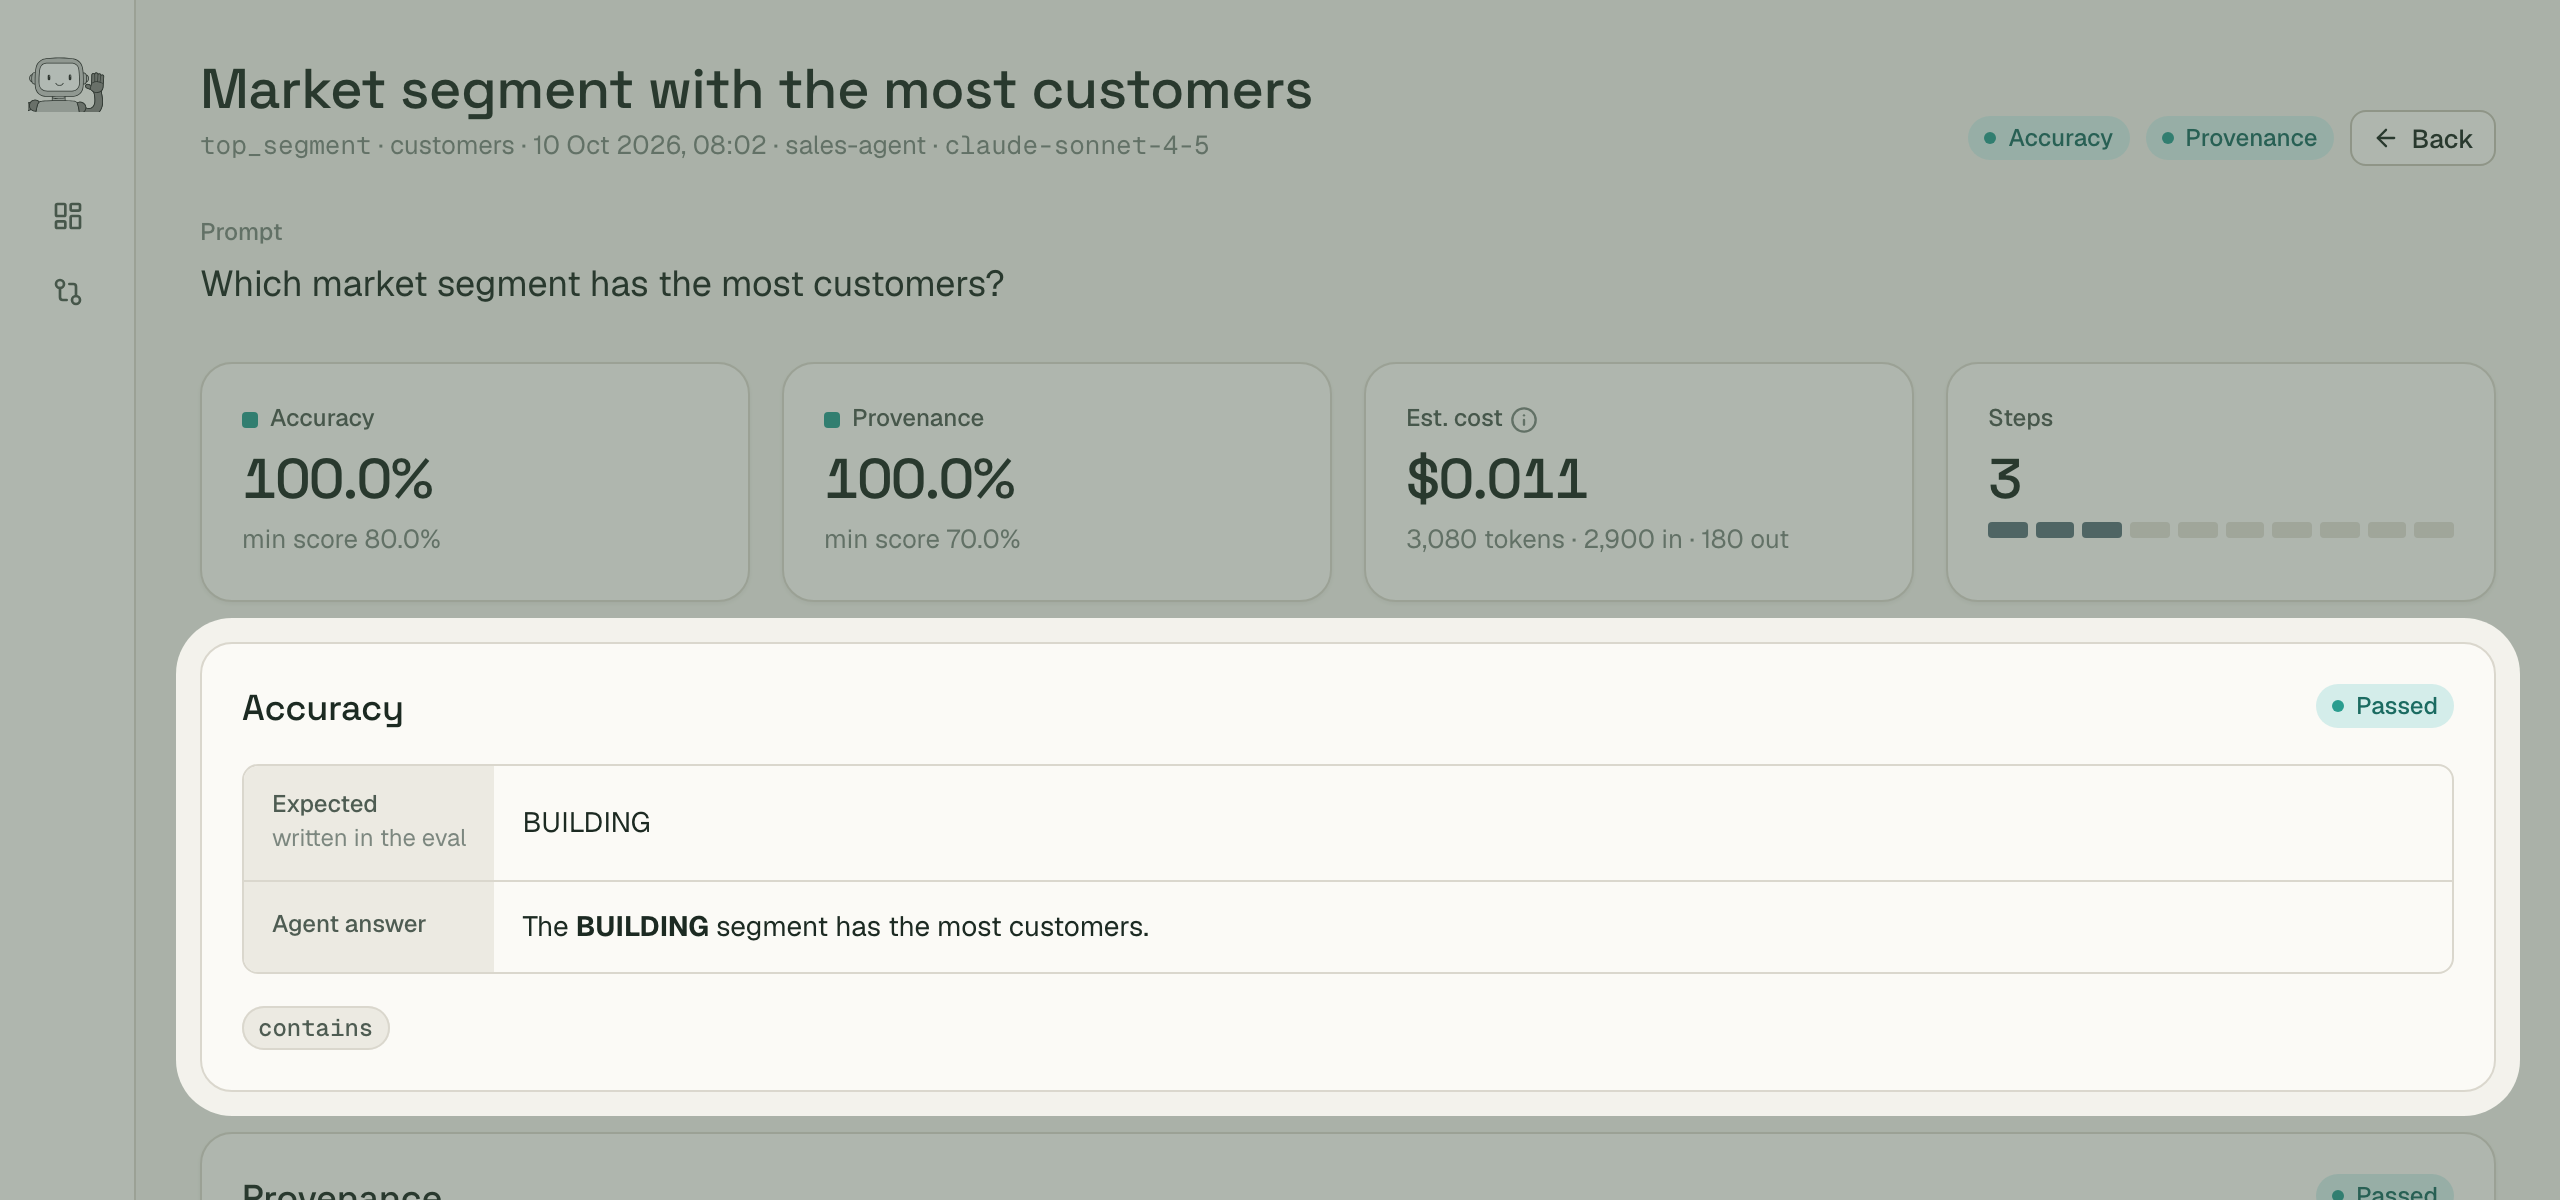
evals: - category: customers grading: method: contains tests: - id: top_segment title: Market segment with the most customers prompt: Which market segment has the most customers? expected_answer: BUILDING
extract_match
A model pulls the value out of the agent's answer, then code compares it with the expected one, within an optional tolerance.
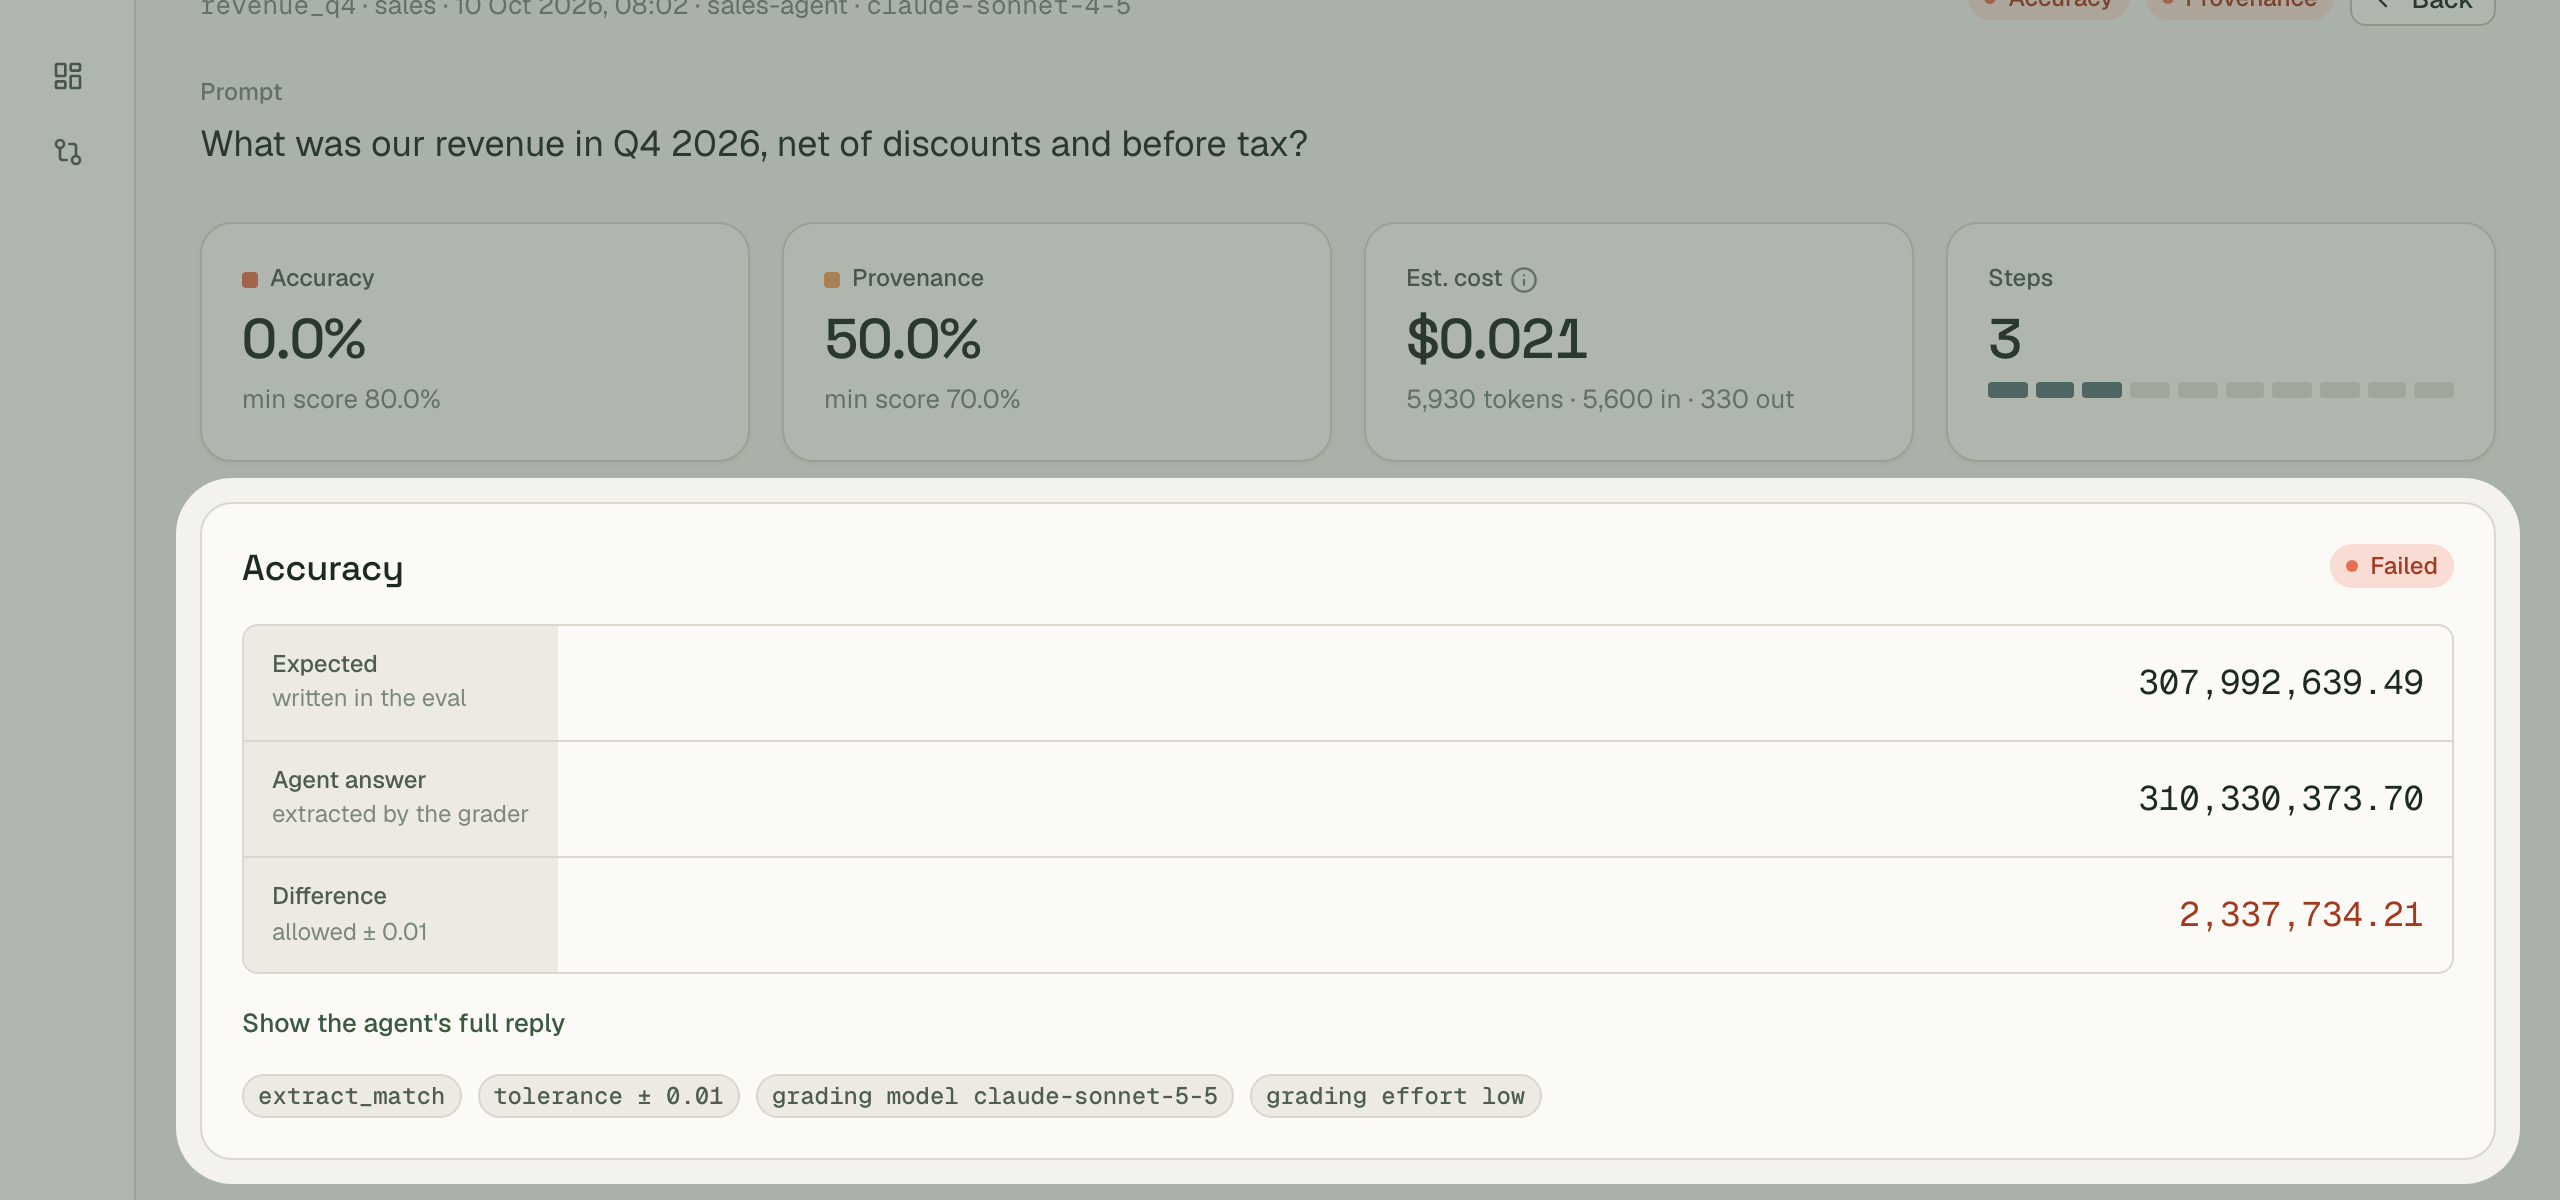
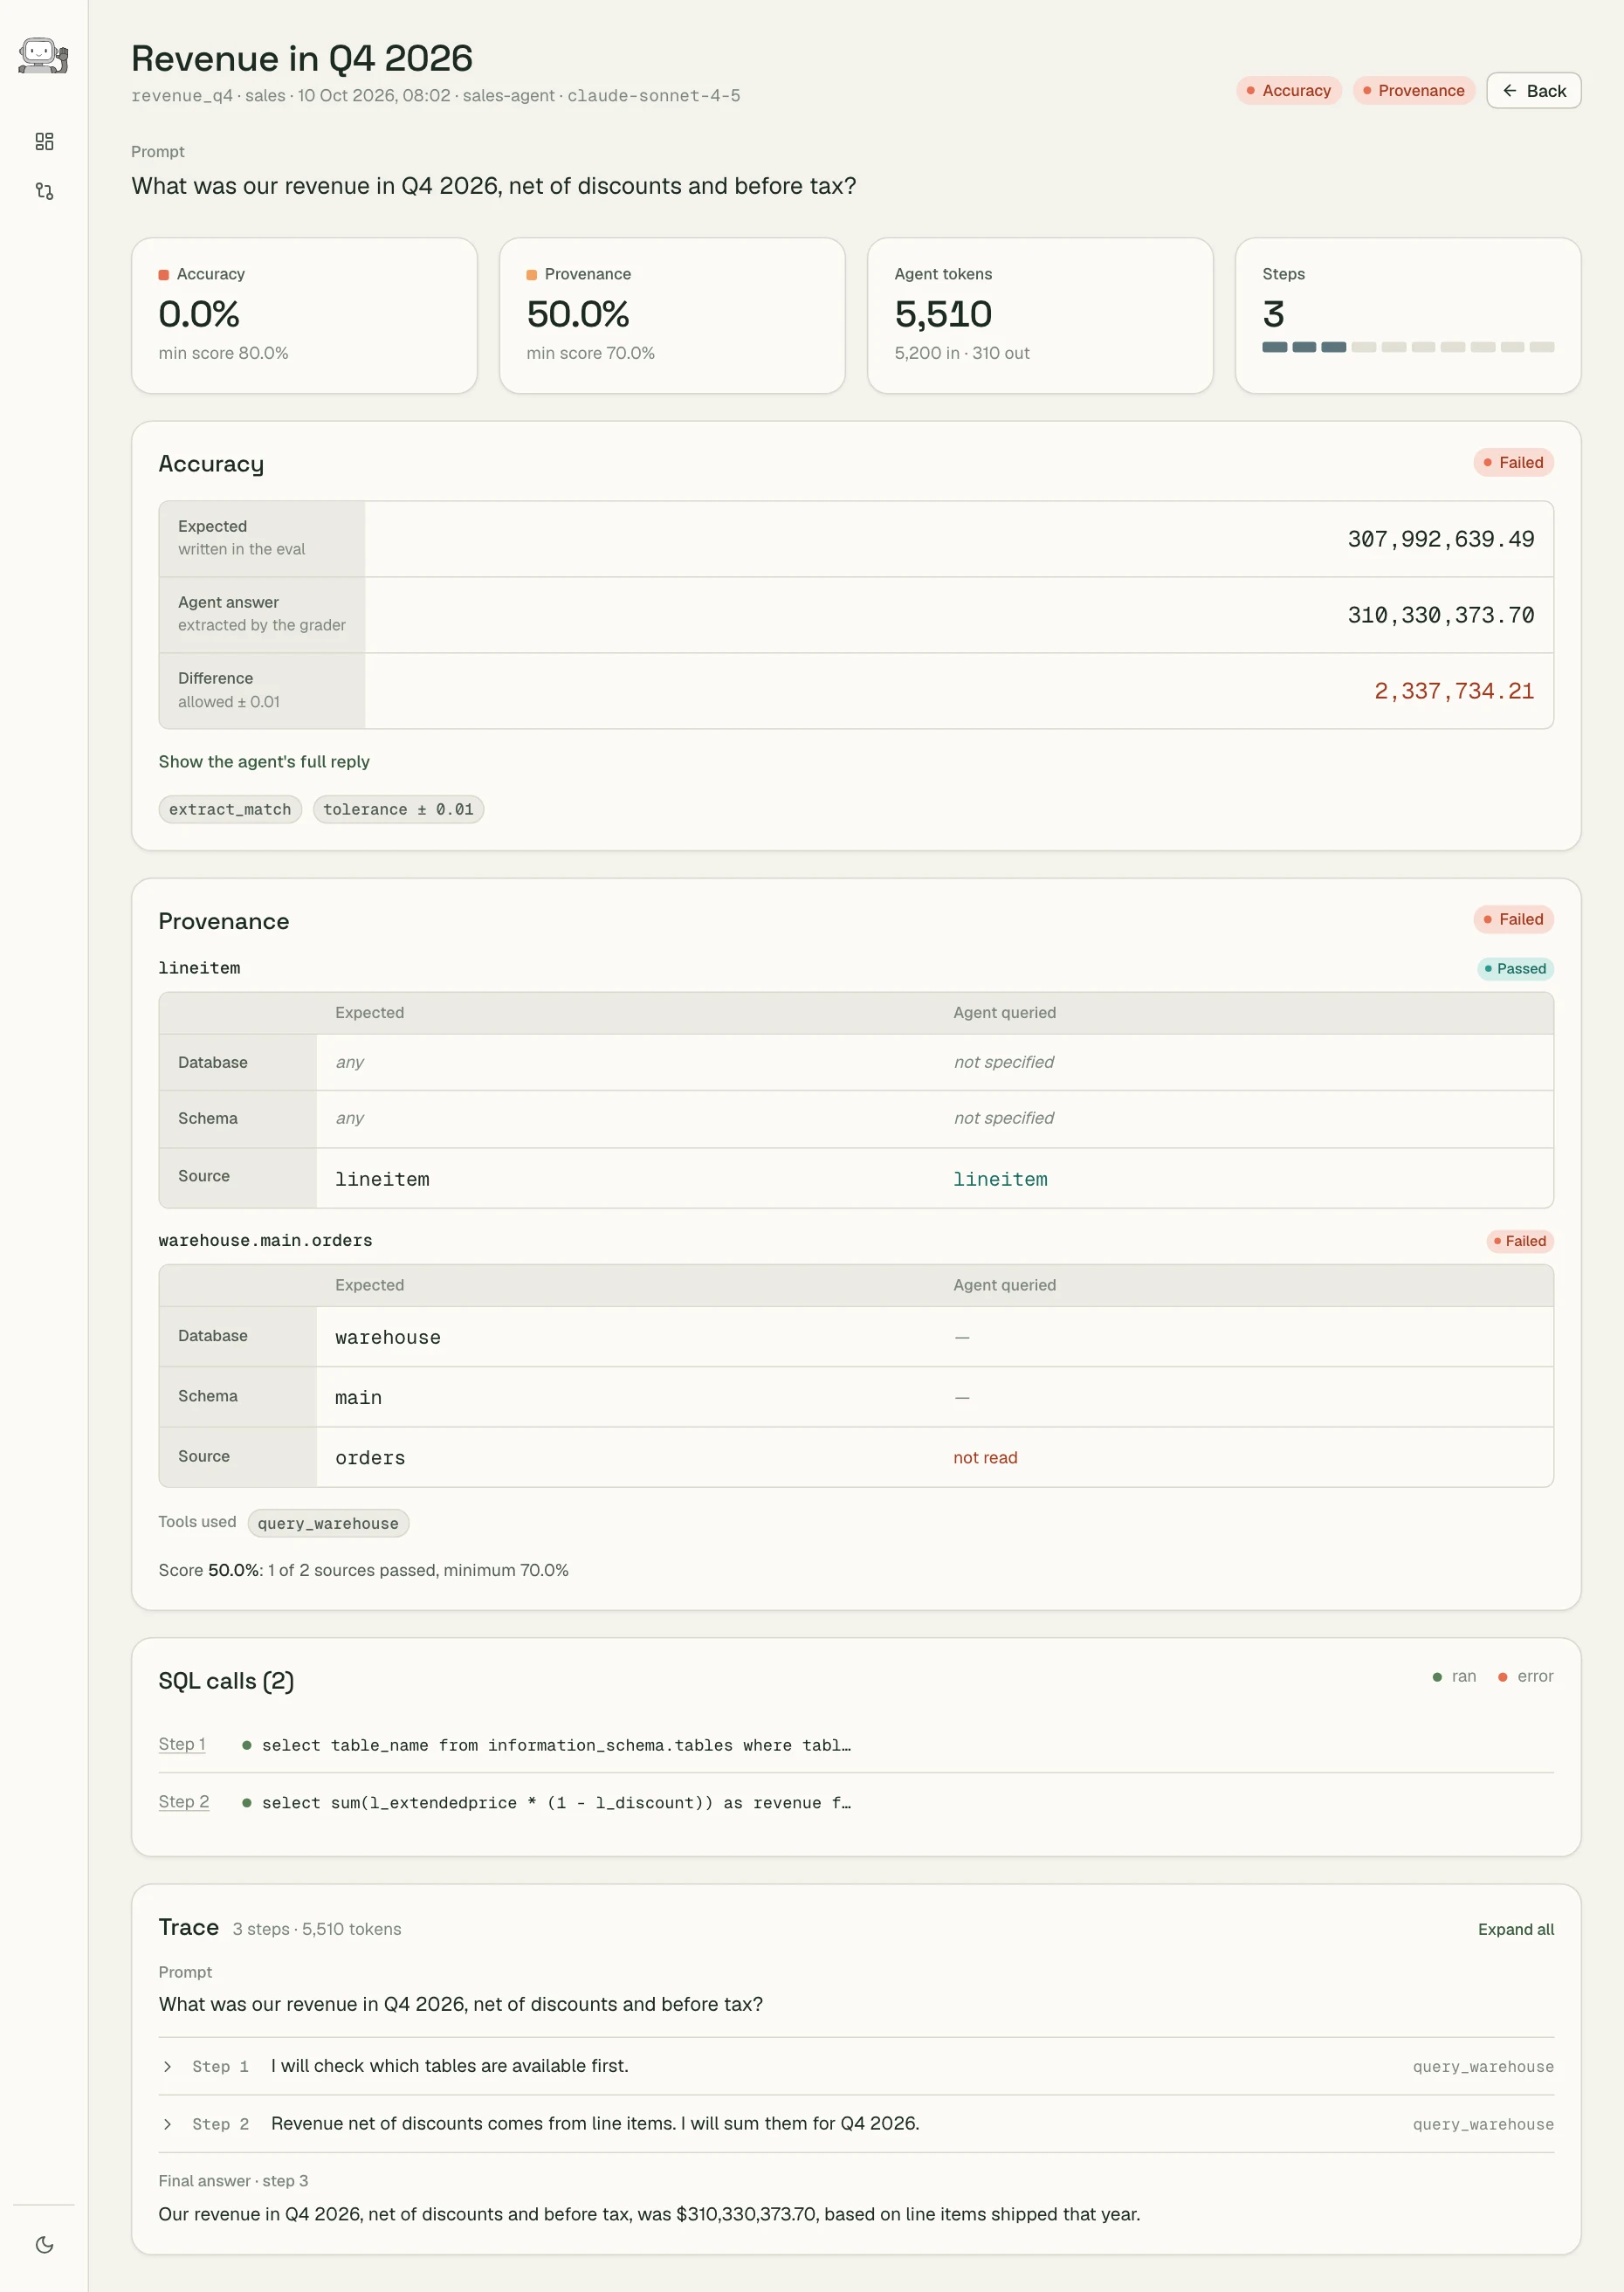
evals: - category: sales grading: method: extract_match min_score: 0.8 tests: - id: revenue_q4 title: Revenue in Q4 2026 prompt: What was our revenue in Q4 2026, net of discounts and before tax? expected_answer: "307992639.49" grading: tolerance: 0.01 # an absolute difference that still counts as equal
llm_judge
The grading model scores the agent's answer against the expected one, from 0 to 1, and explains why.
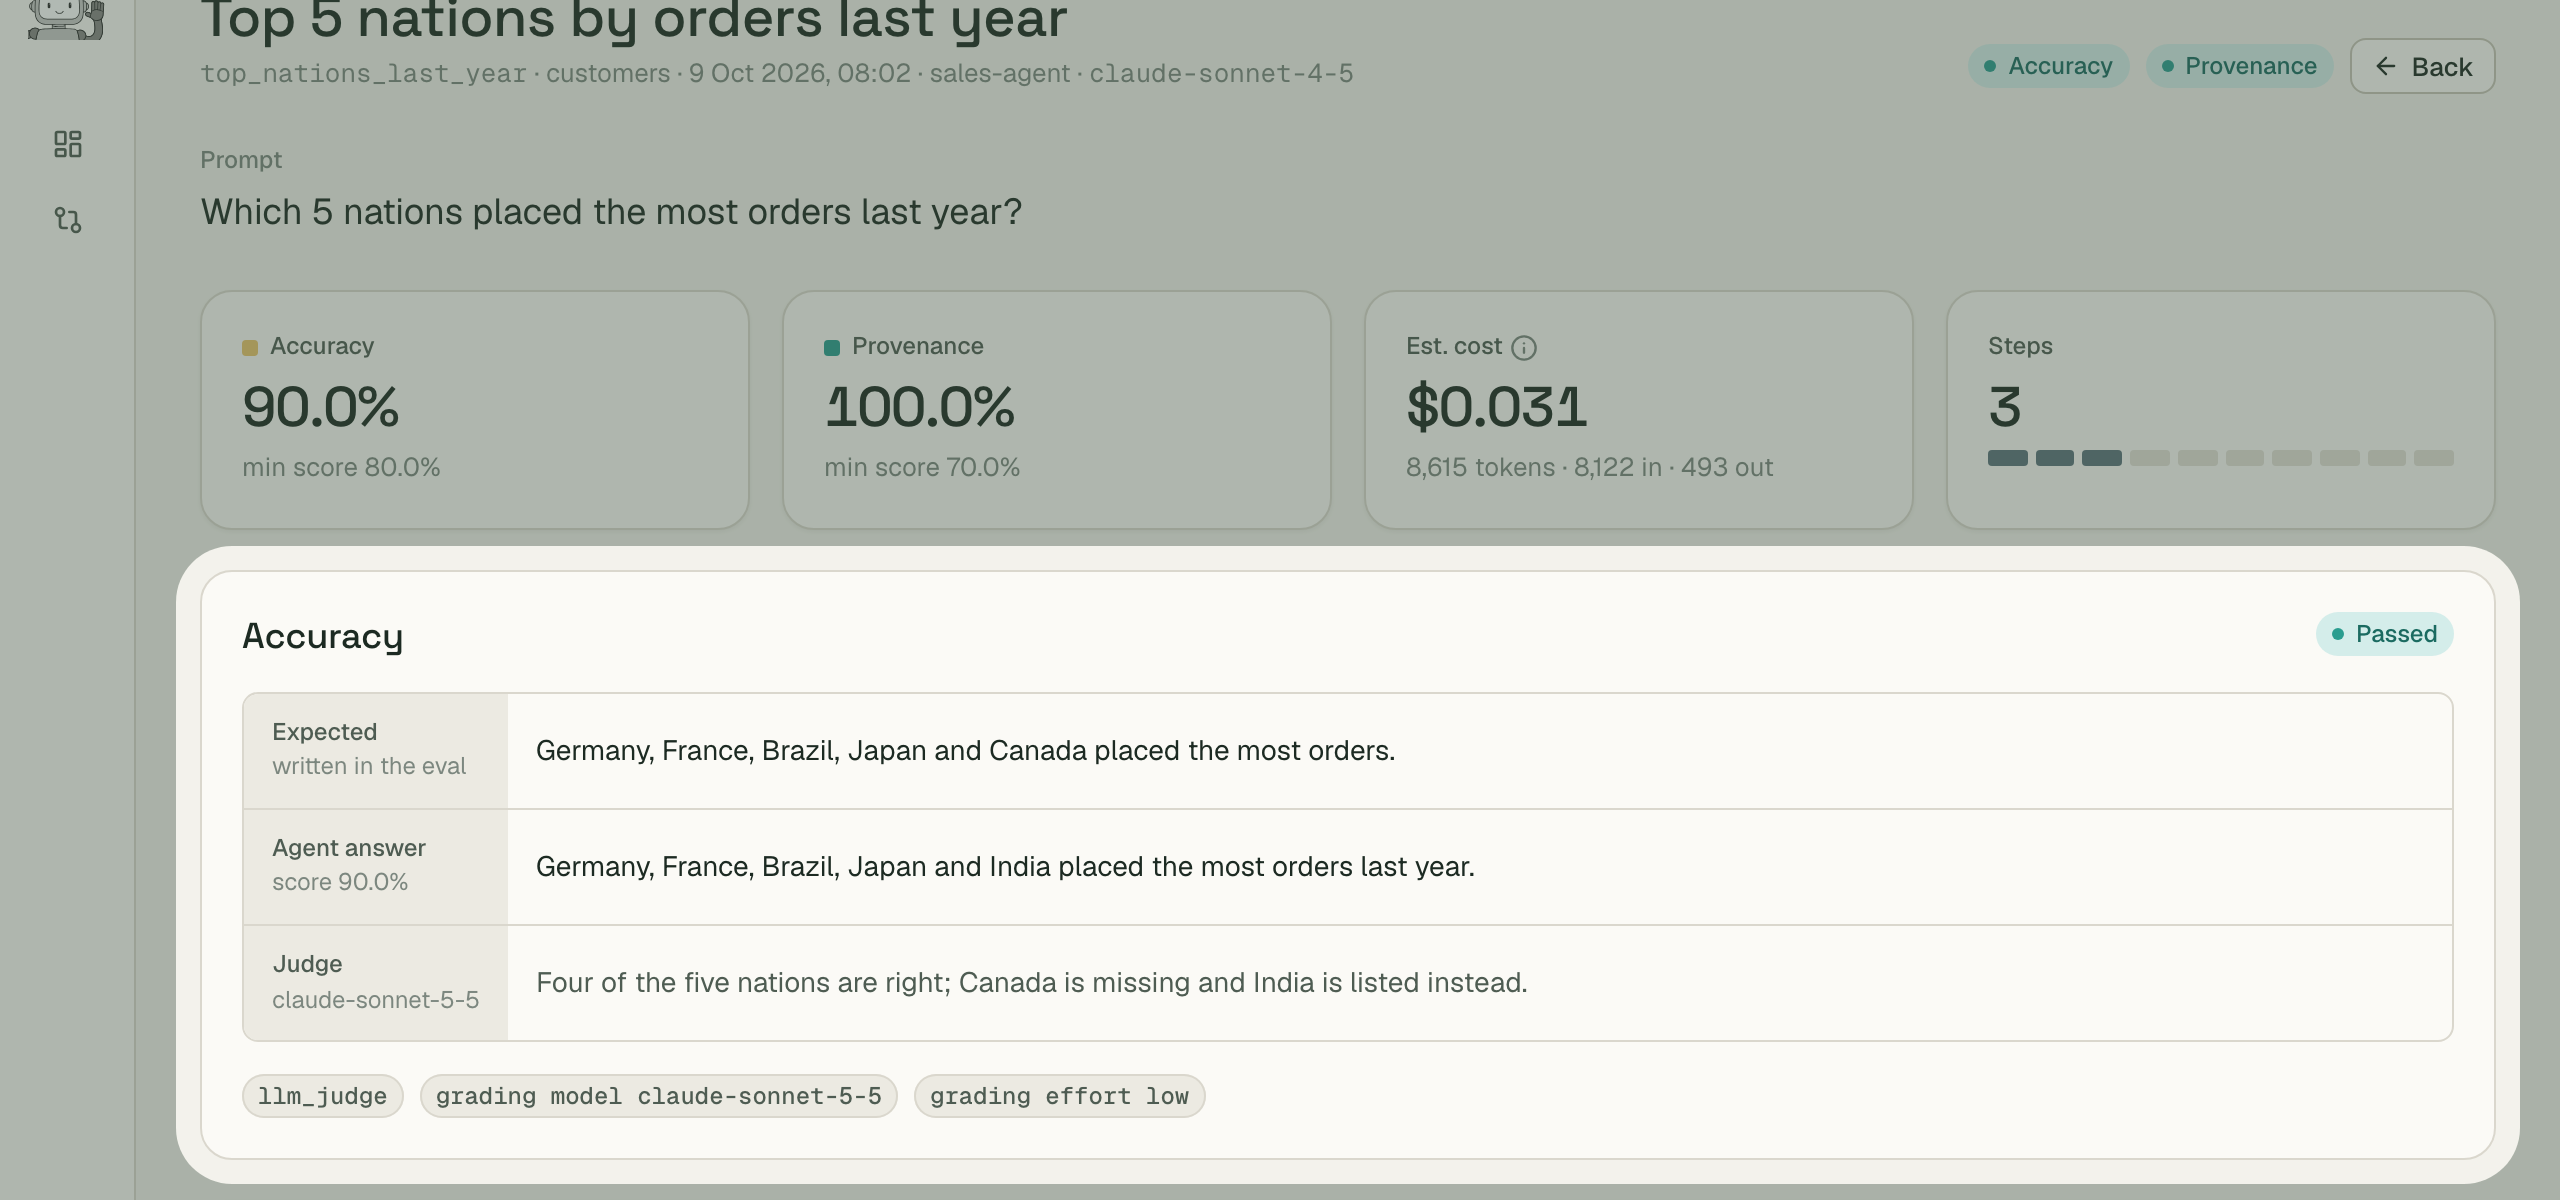
evals: - category: customers grading: method: llm_judge min_score: 0.8 tests: - id: top_nations_last_year title: Top 5 nations by orders last year prompt: Which 5 nations placed the most orders last year? expected_answer: "Germany, France, Brazil, Japan and Canada placed the most orders." provenance: expected_sources: [orders, customer, nation]
Provenance
Checks that your agent queried the sources you expect.
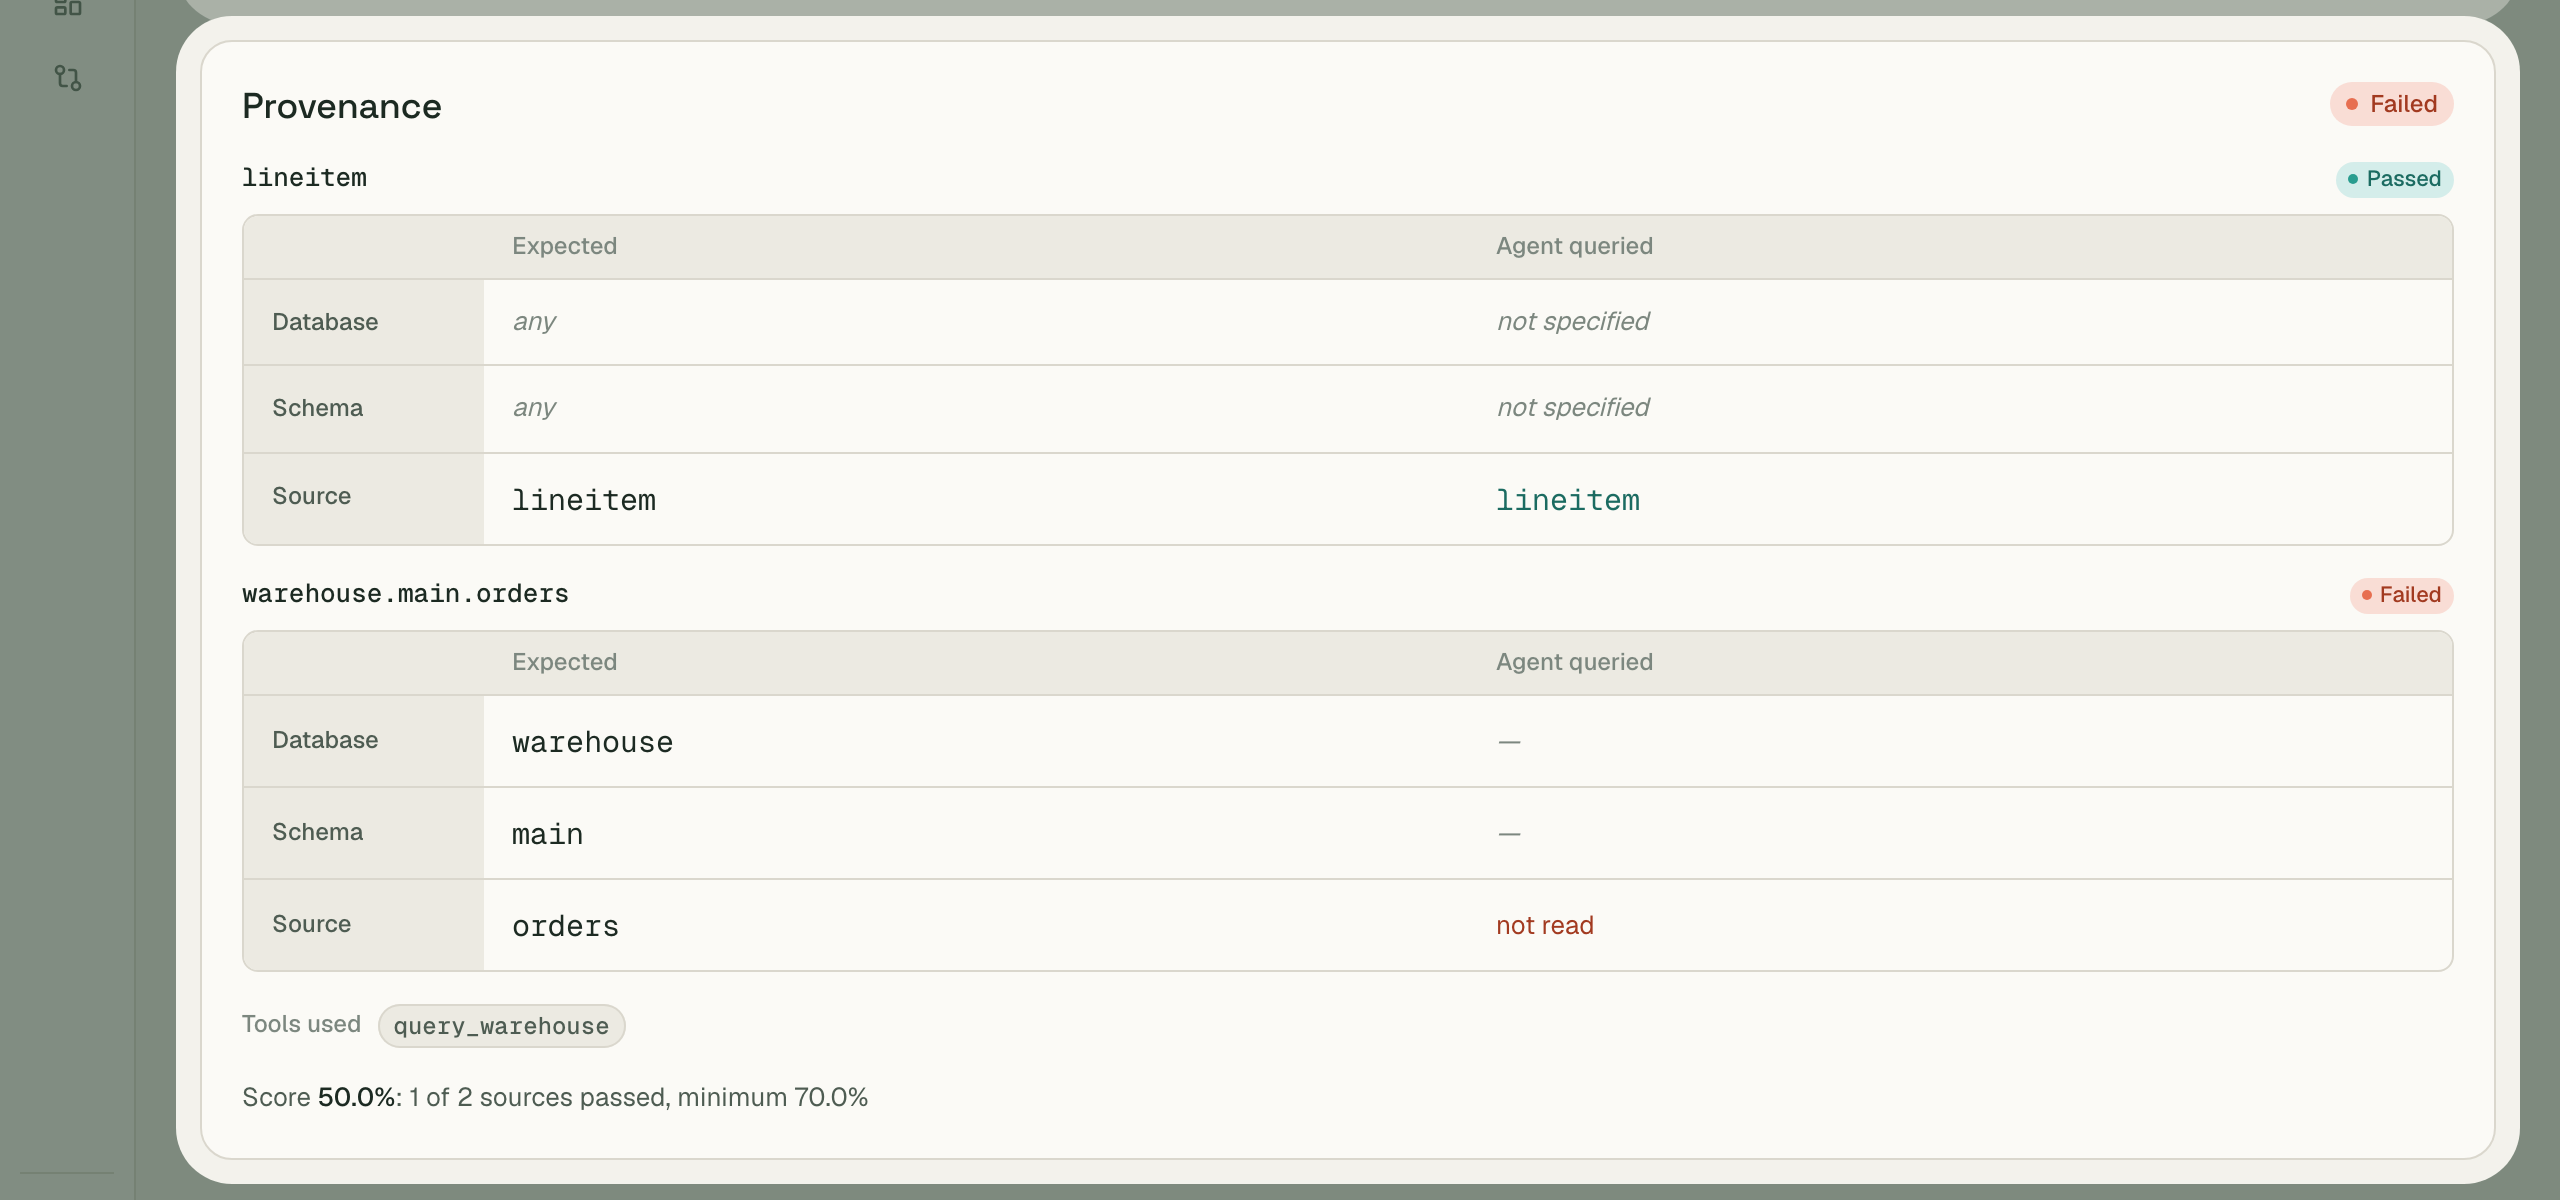
evals: - category: sales provenance: min_score: 0.7 tests: - id: revenue_q4 title: Revenue in Q4 2026 prompt: What was our revenue in Q4 2026, net of discounts and before tax? expected_answer: "307992639.49" provenance: expected_sources: [lineitem, warehouse.main.orders] # database.schema.table
Run your evals in three simple commands
Run your evals, build the report, and open it in your browser.
Run all your evals, or pick a category, a tag or a single eval.
Builds the report from your recent runs into a folder, honest_agent_report by default.
Opens the report in your browser, or host it for your team.
See what failed, and why
The report shows every run of your evals, compares models, and opens each answer.
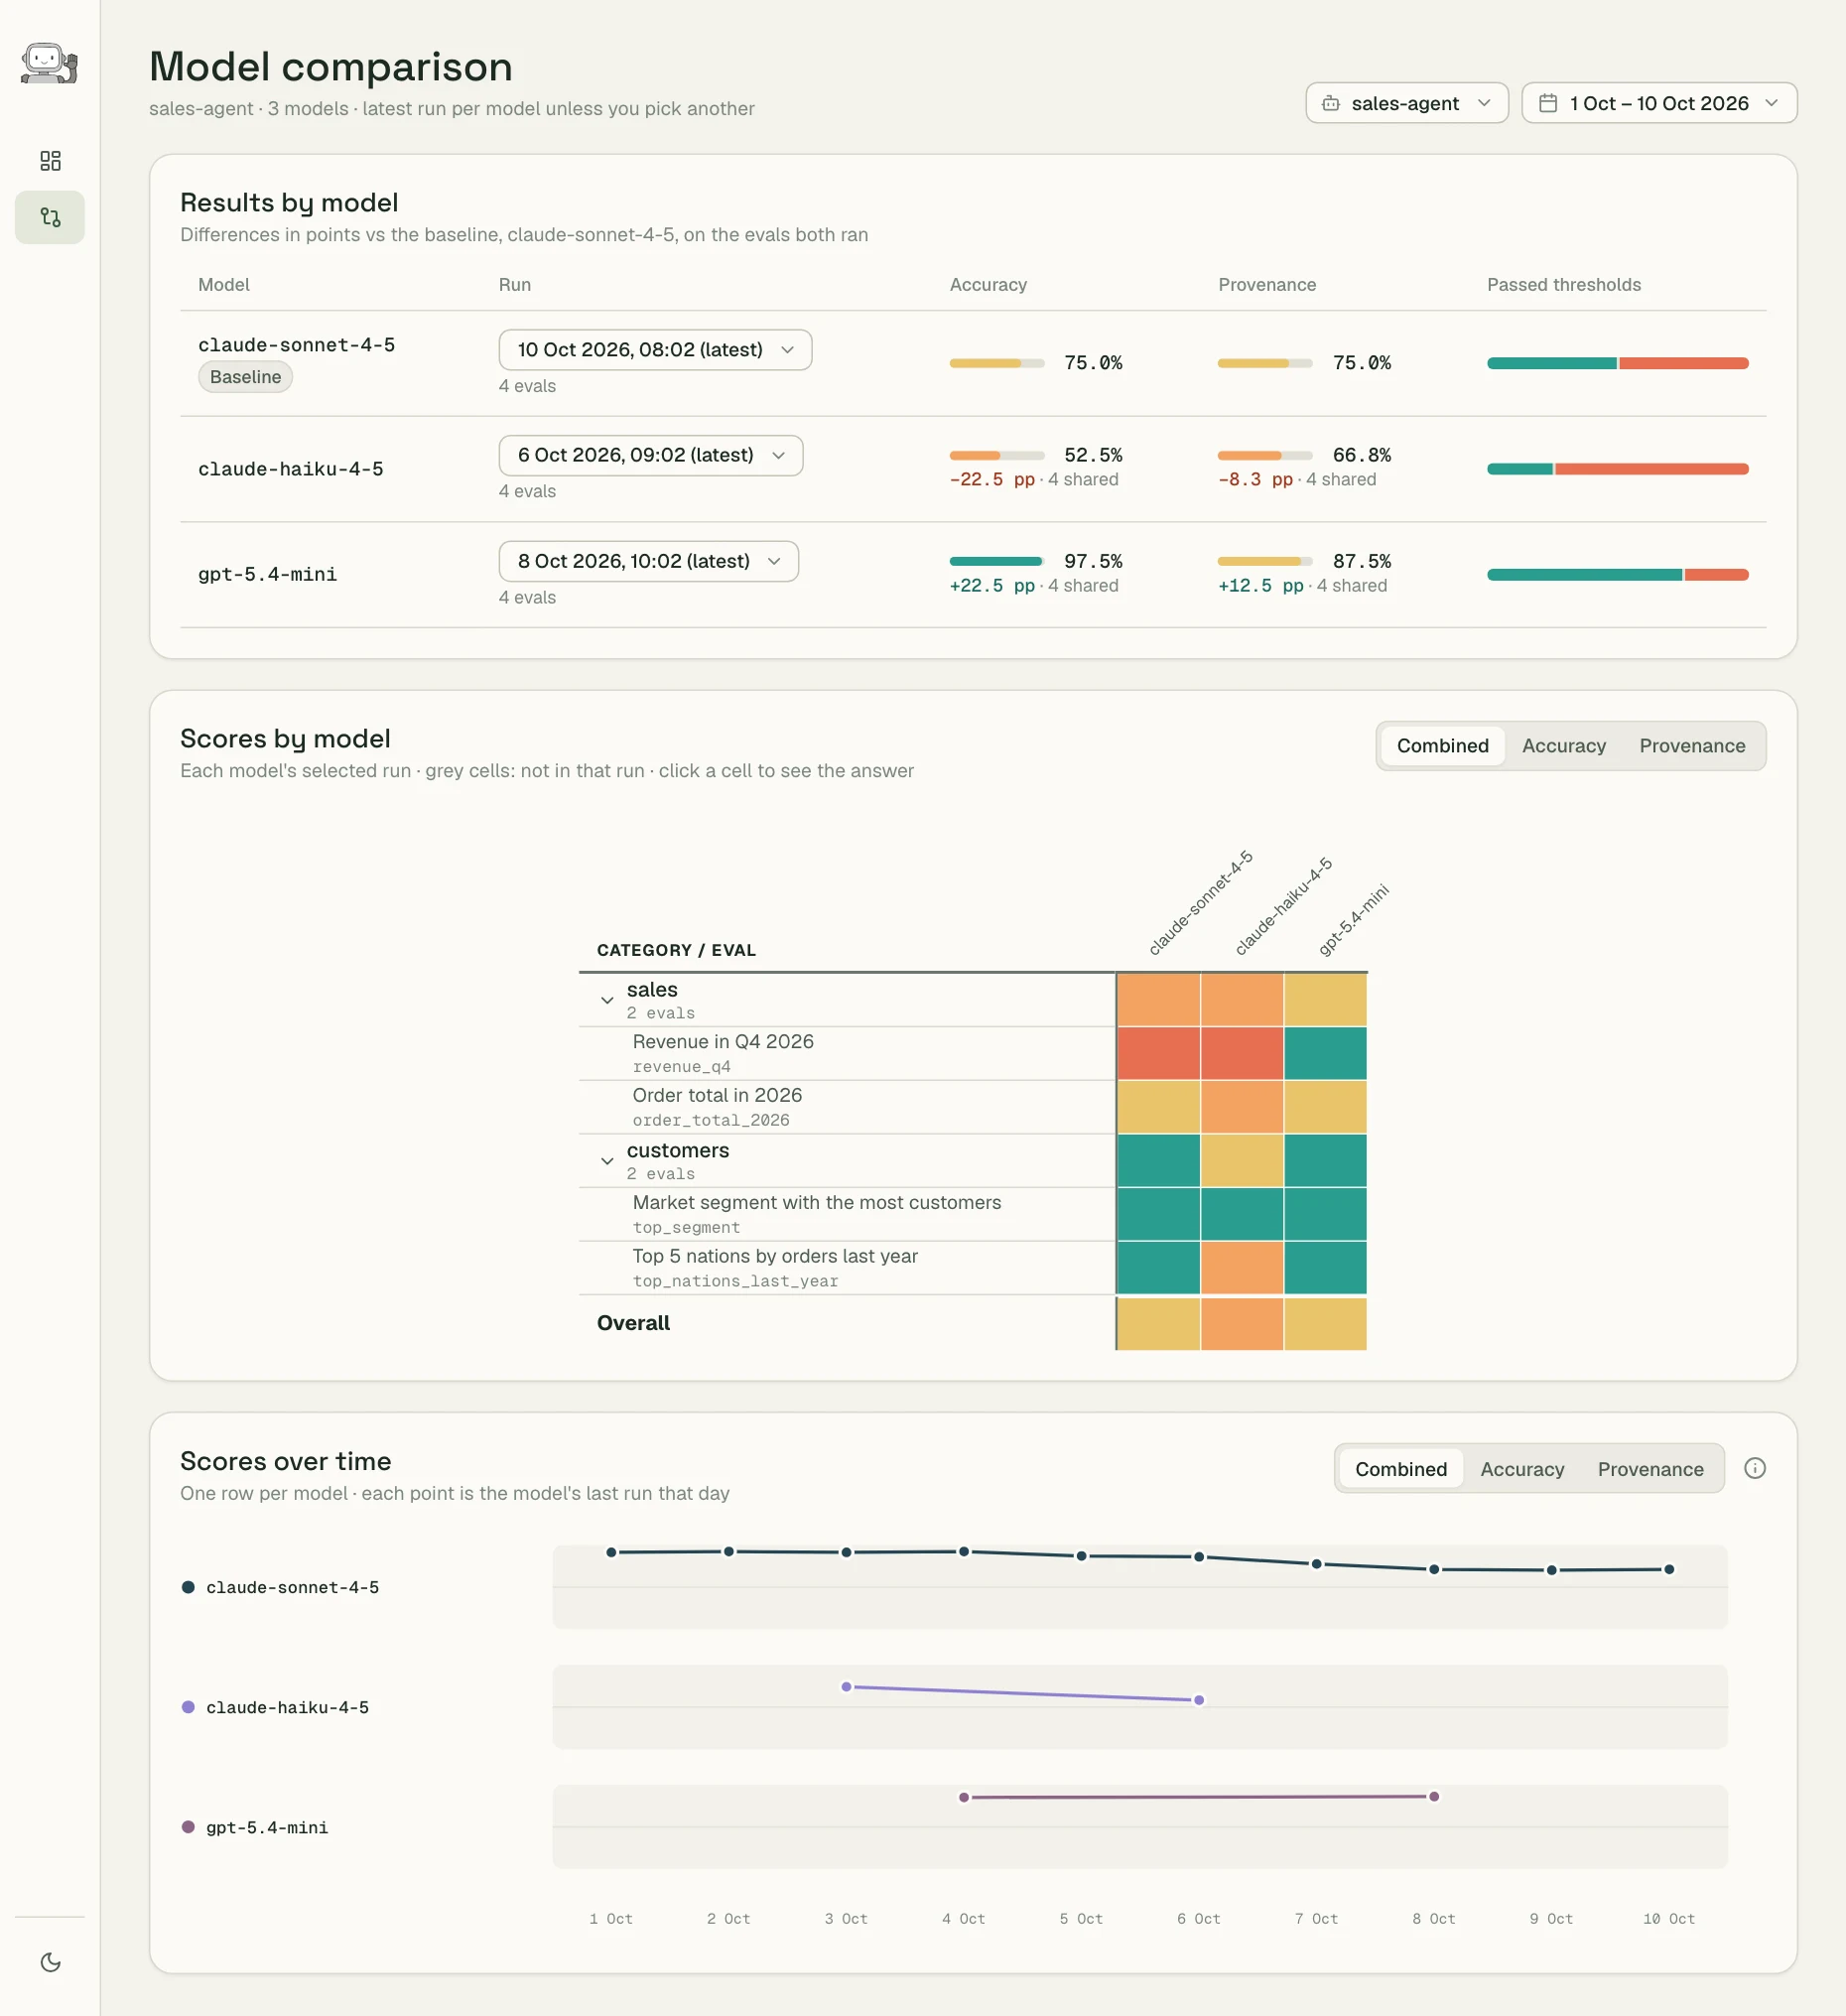
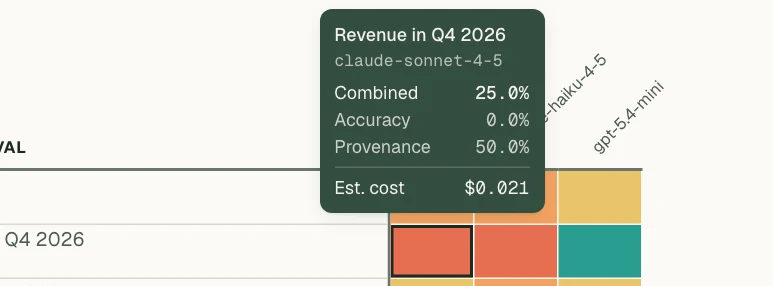
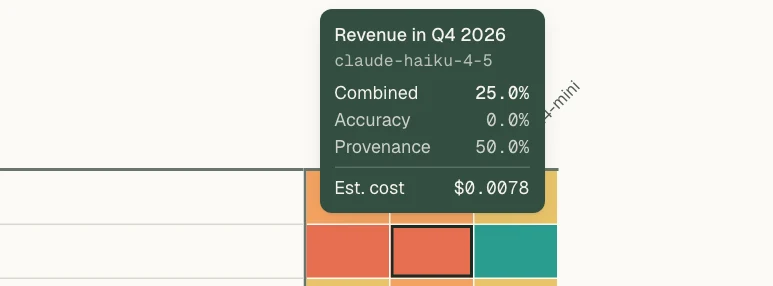
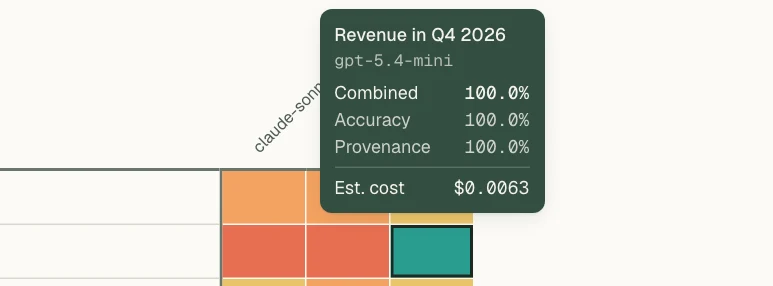
🔴 2 of 4 evals below threshold
orders. Pointed it at orders.o_orderdate in our semantic layer. Rerunning.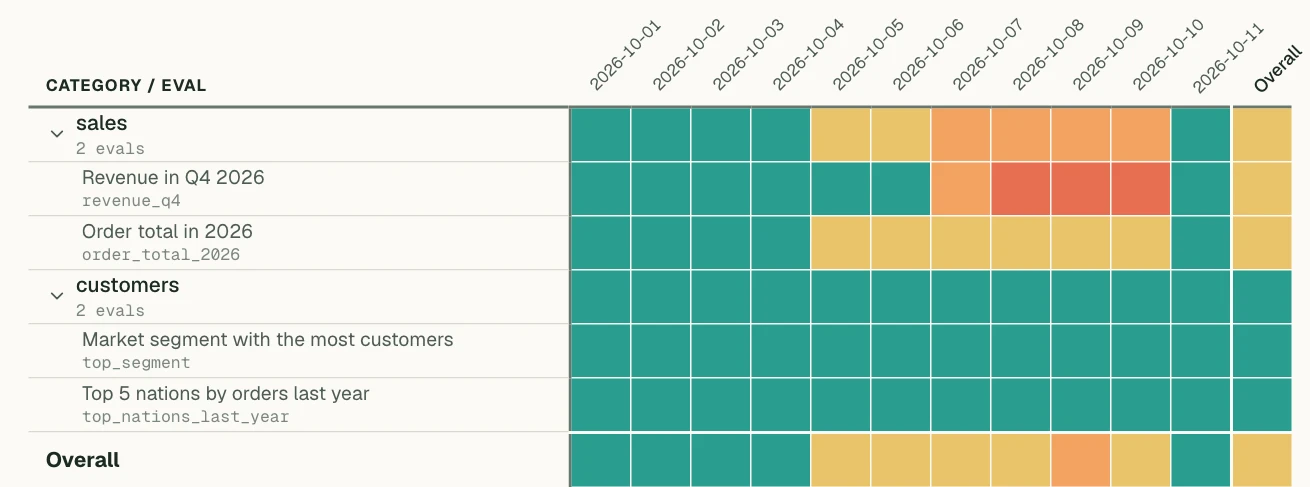
Catch it, fix it, prove it
honest-agent tells you when an eval breaks. After you change your agent, one run proves the fix.
Read the docs on setting up alerts →
Frequently asked questionsFAQ
What does honest-agent test?
An AI analytics agent: the model your agent runs on, with the tools from your agent's own MCP server. It asks questions you know the answers to, and checks two things about each answer: is it right (accuracy), and did it come from the sources your team trusts (provenance).
Does it work with my MCP server?
Yes, if the server is reachable by URL or started with a local command: Snowflake's managed MCP server, MotherDuck, or your own. To check provenance, the server's tools need to take SQL.
Which models can I test?
Claude and OpenAI (GPT) models, with your own API key. To compare models, run the same evals with each one and compare their accuracy and provenance.
What does the report show?
The report is a small website built from your results. It shows each eval's scores over time, the evals below their thresholds, and a page for every answer: what the agent said, what you expected, the SQL it ran, the sources it read, and why it passed or failed.
Can I run it in my pipelines and share the report?
Yes. Run the evals on a schedule or in CI, for example GitHub Actions, and keep the results in MotherDuck or in cloud storage. The report is a static website: host it for your team behind a sign-in, for example on Cloudflare Pages or AWS. A Slack alert tells the team when an eval falls below its threshold.
Can it change my data?
honest-agent refuses SQL that would change your data before it reaches your MCP server: only reads get through. But the agent can use every tool the server offers, and honest-agent can only check SQL. If the server has other tools that change things, such as one that deletes a customer, honest-agent can't block them. Read-only credentials can, so give the server those.
Is it free?
Yes. honest-agent is open source (MIT) and runs on your machine or in your CI. You only pay your model provider for the calls each run makes.
How is it different from the evals built into my warehouse or BI tool?
Those run inside one vendor's product. honest-agent runs from the command line against any MCP server, keeps the results in your own DuckDB file or MotherDuck database, and checks the sources behind every answer.